In high-throughput local AI inference, the primary bottleneck constraining generative language models is not arithmetic compute density—it is memory bandwidth. When serving large transformer models autoregressively, every single generated token requires reading every parameter weight from high-bandwidth GPU memory (HBM or GDDR6X) into register caches, leading to low compute arithmetic intensity and leaving tensor cores idle for 80% to 90% of clock cycles. In 2026, speculative decoding has emerged as the definitive architectural breakthrough in vLLM to bypass this memory bandwidth wall, delivering 1.8x to 2.8x wall-clock speedups without a single floating-point loss in target model output precision.
By pairing a high-capacity target model (such as LLaMA 3.3 70B, Qwen 2.5 72B, or DeepSeek-R1 distillations) with a lightweight draft mechanism, speculative inference decouples token generation from single-token sequential memory access. Whether deploying a separate small autoregressive model, a tree-based feature predictor like EAGLE-2, or multi-head non-autoregressive extensions like Medusa, choosing the correct speculative drafting pipeline dictates whether your local inference rig achieves 85 tokens per second or suffers severe latency regressions from draft verification thrashing.
Speculative decoding shifts inference from memory-bound sequential token generation to compute-bound batch verification. On a target model, verifying K candidate tokens in parallel takes virtually identical GPU execution time as generating a single token from scratch. However, speculative decoding is not free: it consumes between 1.2GB and 4.8GB of additional VRAM for draft weights and speculative KV caches. Deploying EAGLE-2 delivers the highest acceptance rates (70%–82%) across complex reasoning, while Medusa minimizes VRAM overhead at the cost of rigid architectural coupling.
The Mathematical Physics of Speculative Decoding: Memory Bandwidth vs. Compute Density
To understand why speculative decoding accelerates local LLMs so dramatically, consider the memory access cost of standard autoregressive generation. For a 70B parameter model quantized to FP8 (requiring approximately 70 GB of VRAM), generating a single token requires transferring 70 GB of weights across the memory bus. On an NVIDIA RTX 4090 with 1,008 GB/s memory bandwidth, the physical time limit to read the weights once is:
T_memory = Model_Size (GB) / Memory_Bandwidth (GB/s)
T_memory = 70 GB / 1008 GB/s ≈ 0.0694 seconds (14.4 tokens/sec theoretical ceiling)
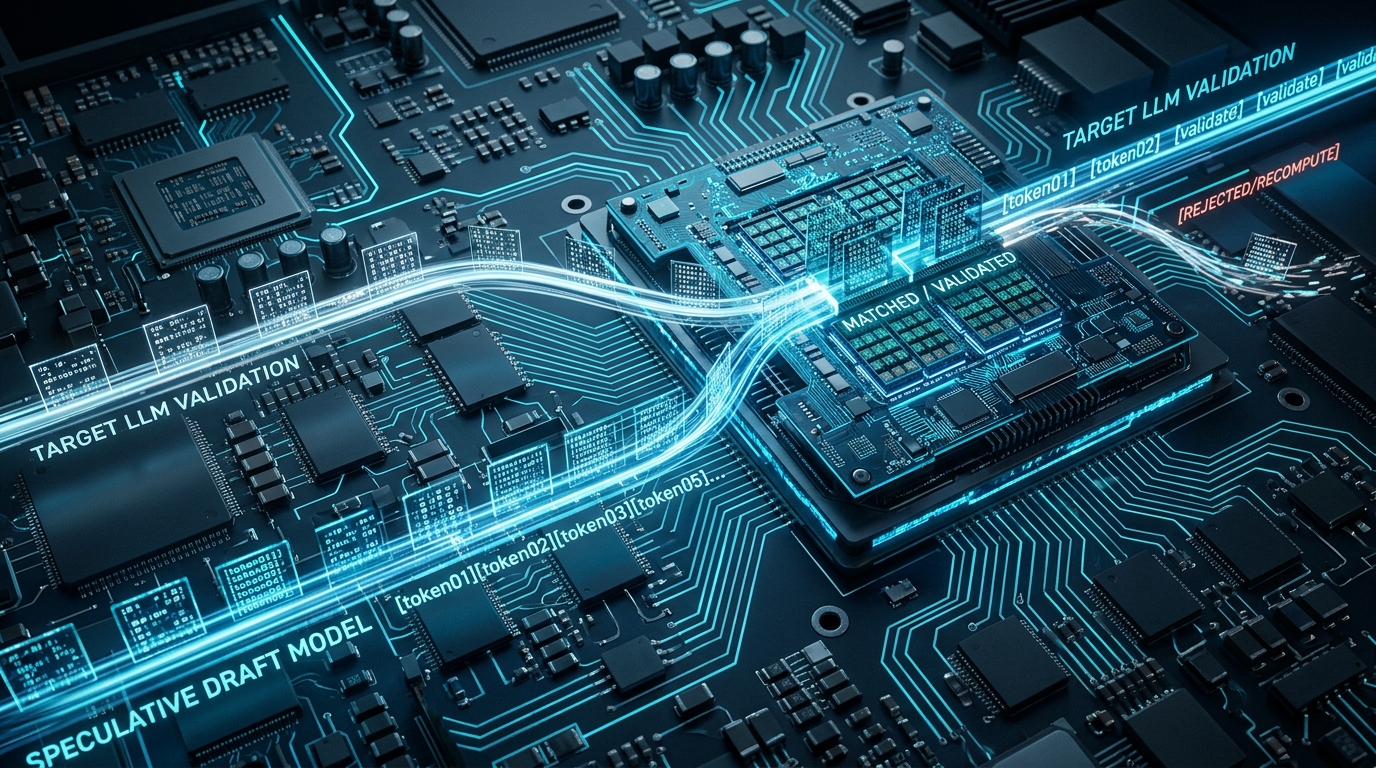
When the target model evaluates an input prompt containing 5 or 10 tokens simultaneously during prefill, tensor cores operate at peak matrix-multiplication efficiency. The weights are fetched from VRAM once and applied across all parallel tokens. Speculative decoding exploits this hardware property by splitting inference into two distinct roles:
- Draft Phase: A small, ultra-fast draft model (such as LLaMA-3.2-1B, taking only 1.2 GB of VRAM and generating at 180+ tokens/sec) quickly generates a speculative sequence of K tokens (typically 3 to 6 tokens).
- Verification Phase: The large target model evaluates all K candidate tokens in a single parallel forward pass using a custom causal verification mask. If the target model agrees with the draft model’s probability distribution up to token m (where m ≤ K), all m tokens are accepted simultaneously, and the target model emits one additional new token for free.
If the average acceptance rate across tokens is denoted by α, the expected number of tokens accepted per speculative iteration is given by:
E[Accepted Tokens] = (1 - α^(K+1)) / (1 - α)When α exceeds 0.75, verifying 4 speculative tokens yields an effective throughput multiplier of 2.2x to 2.6x while maintaining identical greedy or top-p mathematical equivalence to running the massive model standalone. For deep insights into how context caching interacts with token generation speed, review our technical breakdown on prompt caching in local LLMs with vLLM prefix caching.
Draft Architectures: Independent Models vs. EAGLE-2 vs. Medusa
In modern production vLLM clusters, three distinct speculative architectures are deployed. Choosing between them depends directly on your VRAM headroom and the complexity of your reasoning tasks:
| Draft Architecture | Mechanism & Operation | Mean Acceptance Rate (α) | VRAM Overhead | Optimal Hardware Scenario |
|---|---|---|---|---|
| Independent Draft Model | Separate small model (e.g., LLaMA-1B drafting for LLaMA-70B) | 55% – 68% | 2.5 GB – 4.5 GB | Dual GPU rigs with surplus VRAM or standard base models |
| EAGLE-2 (Feature Extrapolation) | Single-layer transformer head drafting on top-level target hidden states with tree attention | 74% – 84% | 1.2 GB – 1.8 GB | Single RTX 4090 / 3090 (24GB) or strict VRAM constraints |
| Medusa Multi-Head | Multiple parallel decoding heads predicting t+1, t+2, t+3 without autoregression | 60% – 72% | 800 MB – 1.4 GB | Fixed base models where trained Medusa weights exist |
| Prompt Lookup / N-gram | Zero-parameter candidate generation matching n-grams directly from input prompt | 45% – 85% (Domain-dependent) | 0 MB (Compute negligible) | Code refactoring, JSON editing, document summarization |
1. Independent Autoregressive Draft Models
The standard baseline approach pairs an architecturally similar model sharing the exact token vocabulary with the primary target. For instance, running meta-llama/Llama-3.2-1B-Instruct as the draft engine for meta-llama/Llama-3.3-70B-Instruct. Because both models share the 128k tokenizer, output token IDs align 1:1. The draft model runs K=4 autoregressive decoding steps inside vLLM, populating a candidate sequence tensor. The primary model then loads the full candidate block into a single matrix calculation. The primary drawback is VRAM overhead: running an independent 1B to 3B model requires its own dedicated model weights and KV cache memory pool, which can trigger out-of-memory crashes on tight 24GB or 48GB configurations. To manage memory allocations effectively, examine our benchmark on KV cache quantization with FP8 and INT4 in vLLM.
2. EAGLE-2: Tree-Structured Hidden State Drafting
EAGLE-2 (Extrapolation Algorithm for Greater Language-model Efficiency) re-engineers speculative drafting by moving the draft process from token space into the target model’s continuous feature space. Rather than executing a standalone LLM, EAGLE uses a single lightweight transformer decoder layer that takes the top hidden states from the target model’s final transformer block. Because hidden states contain vastly denser semantic context than discrete token IDs, EAGLE generates dynamic candidate trees rather than linear token chains.
In vLLM’s implementation, EAGLE-2 dynamically evaluates the confidence scores of draft tree branches, pruning improbable candidate paths before submitting the tree to the target model. This raises the mean acceptance rate (α) from ~62% to over 80% on structured coding and synthetic reasoning benchmarks while requiring less than 1.5 GB of VRAM overhead.
3. Medusa: Parallel Prediction Heads
Medusa eliminates the draft model completely by attaching multiple feed-forward residual heads directly to the last layer of the target backbone. Head 0 predicts token t+1, Head 1 predicts t+2, and Head 2 predicts t+3 concurrently. The generated candidates are assembled into a Cartesian product tree and validated using a custom attention mask in the next forward pass. While Medusa incurs virtually zero draft execution latency, training the heads requires fine-tuning on the target model, making it less flexible than EAGLE when running newly released open weights or fine-tuned checkpoints.
VRAM Allocation & Hardware Budgeting on 24GB vs. 48GB Rigs
Speculative decoding changes your GPU VRAM budgeting equation. In standard inference, VRAM is partitioned into:
Total_VRAM = Model_Weights + Context_KV_Cache + CUDA_OverheadUnder speculative decoding with an independent draft model or EAGLE, vLLM allocates an additional speculative memory pool for the draft model’s weights and speculative KV cache buffers. On an NVIDIA RTX 4090 (24GB) or a dual RTX 3090 (48GB) configuration, improper tuning of --gpu-memory-utilization will cause vLLM to reject the speculative model at launch due to insufficient PagedAttention block pools.
| Hardware Setup | Target Model | Draft Specifier | Target VRAM | Draft VRAM | Baseline vs. Speculative (Tokens/Sec) |
|---|---|---|---|---|---|
| Single RTX 4090 (24GB) | Qwen2.5-Coder-14B (AWQ) | EAGLE-Qwen-14B | 10.8 GB | 1.4 GB | 42 t/s → 96 t/s (2.28x) |
| Single RTX 4090 (24GB) | LLaMA-3.1-8B-Instruct (FP16) | Prompt Lookup (N-gram) | 16.2 GB | 0.0 GB | 88 t/s → 148 t/s (1.68x) |
| Dual RTX 3090 (48GB) | LLaMA-3.3-70B-Instruct (FP8) | LLaMA-3.2-1B-Instruct (FP8) | 38.4 GB | 2.1 GB | 16 t/s → 39 t/s (2.43x) |
| Dual RTX 3090 (48GB) | DeepSeek-R1-Distill-70B (AWQ) | EAGLE-DeepSeek-70B | 36.2 GB | 1.8 GB | 19 t/s → 48 t/s (2.52x) |
Production Implementation: Deploying Speculative Decoding in vLLM
Executing speculative decoding in vLLM requires configuring the OpenAI-compatible API server with explicit speculation parameters. The following production examples demonstrate how to launch both an independent draft model pipeline and an EAGLE-2 tree acceleration pipeline.
Example 1: Independent Draft Model on Dual GPUs (Tensor Parallelism = 2)
In this deployment, an FP8-quantized LLaMA 3.3 70B model serves as the target across two GPUs, while LLaMA 3.2 1B acts as the draft model. Notice the inclusion of --speculative-draft-tensor-parallel-size 1 to avoid wasting tensor communication overhead on the lightweight draft model:
vllm serve meta-llama/Llama-3.3-70B-Instruct --tensor-parallel-size 2 --speculative-model meta-llama/Llama-3.2-1B-Instruct --num-speculative-tokens 5 --speculative-draft-tensor-parallel-size 1 --gpu-memory-utilization 0.92 --max-model-len 8192 --kv-cache-dtype fp8 --port 8000Example 2: EAGLE-2 Tree Acceleration on Single RTX 4090
To deploy EAGLE-2 acceleration on a single 24GB card using an AWQ quantized coding model, specify the EAGLE head repository using the --speculative-model parameter along with speculative tree sizing:
vllm serve Qwen/Qwen2.5-Coder-14B-Instruct-AWQ --speculative-model yuhuili/EAGLE-Qwen2.5-Coder-14B-Instruct --num-speculative-tokens 4 --gpu-memory-utilization 0.88 --max-model-len 16384 --enforce-eager --port 8000For high-concurrency environments comparing engine performance under multi-client loads, cross-reference our comparative benchmark between vLLM and SGLang running FlashAttention-3.
Speculative decoding is one of the rare optimizations in machine learning that provides a dramatic speedup with zero quality degradation. However, it introduces two failure modes you must monitor in Grafana: acceptance rate collapse and VRAM thrashing. If your draft model’s acceptance rate drops below 45% (common when running highly creative prose generation or extreme low-temperature mathematical logic), the computational cost of running draft generation and tree masking exceeds the cost of pure autoregression, causing net throughput to degrade by 10% to 15%. For production code generation, API formatting, and structured summaries, EAGLE-2 configured with K=4 or K=5 candidate tokens represents the premier price-to-performance configuration on modern consumer GPUs.
Where to Expand Your Stack Next
- Quantization Math: Deepen your inference efficiency with our breakdown on FP8 vs. INT4 KV Cache Quantization in vLLM.
- Prefix Caching: Slash Time-to-First-Token (TTFT) across long multi-turn sessions using Prompt Caching & Prefix Caching in Local LLMs.
- Multi-GPU Topology: Scale your server rack with our complete blueprint for Dual RTX 3090 (48GB) Local AI Clusters.
People Also Ask
Does speculative decoding reduce the output quality or accuracy of the target LLM?
No. Speculative decoding guarantees strict mathematical equivalence to running the target model standalone. The target model evaluates the draft tokens against its own probability distribution using identical sampling criteria (temperature, top-p, min-p). Any token that fails the verification threshold is rejected and re-sampled directly from the target model’s logits.
What happens when a draft token is rejected during verification?
When a draft token fails verification at index m, the speculative iteration terminates at that position. All previously validated tokens up to m-1 are appended to the output context, the target model generates the correct token for position m, and all subsequent speculative tokens (m+1 to K) are discarded without executing additional forward passes.
How much additional VRAM does speculative decoding require in vLLM?
VRAM requirements vary by architecture. Independent draft models (such as LLaMA-3.2-1B) require between 2.0GB and 4.5GB of VRAM for weights and KV cache space. EAGLE-2 requires only 1.2GB to 1.8GB, while prompt-lookup (n-gram) decoding requires 0GB of additional VRAM.
Can I use speculative decoding with quantized models like AWQ, GPTQ, or FP8?
Yes. vLLM fully supports speculative decoding where both the target model and the draft model are quantized in FP8 or AWQ. You can pair an FP8 target model with an FP8 draft model or use unquantized draft heads like EAGLE directly alongside quantized target weights.